For months, a sprawling network of automated content farms—anchored by properties like WHYS.video, AskAbout, and Language Foundation—has churned out tens of thousands of programmatic videos and articles. Behind the facade of a polished digital media operation lies a web of automated scraping, proxy manipulation, and deceptive corporate structuring designed to game search engine algorithms at scale.
This is the forensic breakdown of how Mass Presence Kft. built, operated, and scrambled to defend its industrial-scale AI content empire.
1. Technical Lineage: From Legacy Site-Builders to AI “Slop”
The operational roots of this network trace back to traditional Hungarian web infrastructure and template systems. Reverse-IP analysis ties MassPresence.hu directly to HuPont.hu—a long-standing Hungarian portal and free website-builder platform.
The Template Pipeline: Operating a legacy site-builder network provided the template engines, automated deployment scripts, and scraping scaffolding required to scale content production.
The AI Evolution: Over time, these basic template generators evolved into automated programmatic Q&A scrapers and generative AI “slop” farms. Ghost subdomains and legacy test accounts created on these platforms continue to receive automated platform migration notices regarding a “renewed system”—which is likely just another vibe-coded tool deployed to manage legacy sites automatically.
2. Infrastructure & Corporate Obfuscation
Operating out of Hungary, the network uses classic tactics to obscure its paper trail and evade scrutiny:
Geographic Shell Games: Public corporate listings have shifted registered locations from Hungary to Austria to break investigative chains, while core development and hosting infrastructure remain anchored to Hungarian networks.
Hosting & Proxy Shielding: Operations rely heavily on Hetzner hosting clusters paired with leased proxy ranges (such as IPXO subnets) to mask automated traffic. When blocking these proxy blocks at the WAF level, automated monitoring tools like LohiSoftBot—a Hungarian-origin crawler—reveal attempts to track investigative updates passively.
Residential IP Leaks: Periodic manual visits from operators routing through local ISPs (such as One Hungary) frequently puncture their proxy defenses, exposing true connection metadata right in security event logs.
3. Forensic Markers & Programmatic Glitches
The content produced by the network bears unmistakable programmatic fingerprints:
Aged Artifacts & Glitches: Early video archives feature vintage 2019-era scraping artifacts, including unparsed kaomojis (>_<) baked directly into auto-generated thumbnails.
LLM Vocabulary & Cutoff Hallucinations: Subtitles across their channels rely heavily on repetitive generative buzzwords (“delve,” “crucial”) and classic LLM hallucinations, such as referencing a “September 2021 knowledge cutoff”.
Mass Upload Spikes: Platform metrics captured via tools like Filmot reveal erratic, high-volume upload bursts—sometimes reaching up to 600 videos a day—interspersed with periods of complete dormancy. Despite massive view or subscriber counts, engagement metrics remain negligible, confirming inorganic, automated growth.
4. Identity Correlation & Behavioral Panic
The human anchor of the operation links back to developer profiles tied to the email address [email protected].
Breach Profiles: This address appears across numerous public data breach dumps (including Suno, Trello, Twitter, Gravatar, and credential-stuffing compilations like Naz.API), connecting legacy developer accounts directly to modern generative AI tool usage and automated audio pipelines.
Real-Time Damage Control: Each time structural connections are exposed publicly—such as pointing out shared typography between personal developer sites and WHYS.video, or emailing inquiries regarding deceptive reuploads—the operators immediately scramble. Videos are deleted and re-uploaded within 24 hours, and stylesheets are quietly patched, providing clear behavioral proof that the network is actively monitoring its own exposure.
What began as basic Hungarian web tooling evolved into a high-volume, automated content machine. Despite multi-layered proxy defenses, geographic relocation tricks, and automated crawler bots, the digital paper trail—from reverse-IP lookups and WAF security logs to historical breach data—proves that even the most automated operations leave an indelible signature.
More WHYS.video/Language.foundation/Askabout.video changes happened over the weeks, and here are some of them.
1. The Ipxo hits on my analytics
When I was checking my analytics service, I noticed hits keep coming from an ISP named “Ipxo” and from both Chrome and Firefox on a Linux desktop; it is probably another vibe-coded script checking my website for new updates.
I blocked the Ipxo ASNs on my firewall, so it can no longer scrape my website.
I noticed something similar a few months back, when a bot named “LohiSoftBot” started hitting my website. LohiSoft is a software company, and their Bot started hitting my website many times from Hungary. LohiSoftBot is a bot meant for feeding a search index, and LohiSoft is not a search engine, so it is probably monitoring this website for new blog posts.
I added it to my robots.txt and later my firewall.
2. The language.foundation vibe coded update
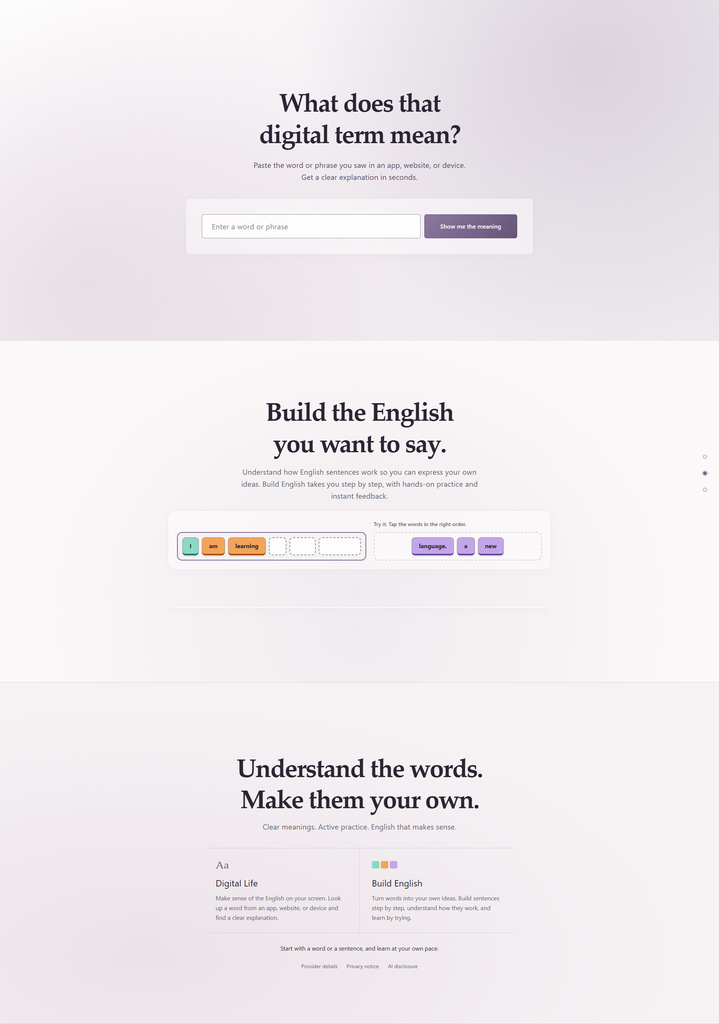
They had updated Language Foundation again, this time with a digital term search. What’s funny if I try to search “hallucination”, “slop”, “vibe coding,” or “content farm” it comes up with no results, despite claiming to describe digital terms.
We’re thrilled to announce a major expansion to LLM Radar: the integration of Allen Institute for AI’s massive WildChat-4.8M dataset!
By combining WildChat’s rich, multi-turn interaction logs with our existing daily token data from OpenRouter, LLM Radar now offers an unprecedented level of real-world intelligence into how large language models are actually being used.
The Strategic Advantage: Beyond Basic Token Counts
Until now, tracking LLM momentum mostly meant looking at top-level API token volume. While high-level usage metrics are critical, they only tell part of the story.
By layering WildChat-4.8M alongside our OpenRouter dataset, LLM Radar bridges the gap between raw API consumption and real-world conversation dynamics:
Real-World Chat Dynamics: Gain visibility into actual user prompts, turn frequencies, language distributions, and multi-turn conversation lengths.
Deeper Historical Context: Trace model usage patterns over longer timeframes across key architectural shifts and model releases.
Model-Specific Granularity: Inspect detailed telemetry for specific model families—such as GPT-4 variants, open-weight models, and reasoning architectures—to see how user interaction styles differ across models.
Why This Matters for Developers & Researchers
Evaluating AI models isn’t just about benchmark scores or published API prices—it’s about how models perform in production under real-world prompt distributions.
With this new dataset integration, LLM Radar users can:
Refine Cost & Token Estimates: Understand actual input-to-output token ratios across real user chats to make the LLM Token Calculator even more accurate.
Analyze User Behavior: See how prompt lengths, system instructions, and multi-turn sessions scale in practice.
Make Data-Driven Architecture Decisions: Choose models based on proven real-world adoption, performance efficiency, and cost viability.
What’s Next?
The addition of WildChat-4.8M marks the next step in our vision to make LLM Radar the ultimate data-driven dashboard for the AI ecosystem. We will continue expanding our datasets, refining our analytics UI, and building tools that make exploring AI models simple, accessible, and actionable.
Discover which large language models are gaining traction, explore historical token usage, compare pricing, and estimate inference costs—all in one place.
The artificial intelligence landscape is evolving at an extraordinary pace. New large language models (LLMs) are released regularly, pricing changes, context windows expand, and developers have more choices than ever before.
But with so many models available, one important question remains:
How do you know which AI models are actually being used?
That’s why we created LLM Radar, a data-driven platform designed to make exploring and understanding the LLM ecosystem easier.
Whether you’re an AI developer, researcher, startup founder, or simply curious about the latest AI models, LLM Radar helps you look beyond benchmarks and marketing claims to explore real-world usage trends.
What Is LLM Radar?
LLM Radar is an AI model analytics platform that combines historical token usage statistics with model specifications and pricing information from OpenRouter.
Instead of jumping between different websites to research models, LLM Radar brings useful information together in an intuitive dashboard.
With LLM Radar, you can:
Explore historical token usage: See how model activity changes over time.
Identify trending models: Discover which models are experiencing increased usage.
Compare model popularity: Understand how models rank based on recorded token consumption.
Examine model specifications: Review context windows, output limits, and supported modalities.
Analyze pricing: Compare published input and output token rates.
Estimate inference costs: Calculate approximate API expenses using the companion LLM Token Calculator.
The goal is simple: make LLM usage data more accessible, understandable, and actionable.
Go Beyond AI Benchmarks
Benchmarks are useful for evaluating model capabilities, but they don’t tell the whole story.
A model might perform exceptionally well on coding, reasoning, or mathematics benchmarks while seeing relatively little real-world usage.
Conversely, a smaller, more affordable model might attract substantial usage because of its speed, accessibility, or cost efficiency.
LLM Radar provides another perspective by examining token consumption across models represented in its historical dataset.
Track Token Usage Over Time
One of LLM Radar’s core features is its historical token usage dashboard.
Search for a supported model and explore statistics such as:
Total recorded tokens
Average daily token usage
Peak usage days
Recent usage trends
Relative usage rankings
Interactive charts make it easier to identify changes in model activity over time.
For example, you might discover that a newly released model is gaining adoption rapidly or that an established model is maintaining consistent demand despite growing competition.
These observations can provide useful context when evaluating the changing AI ecosystem.
It’s important to note that token usage reflects activity within the dataset’s coverage, not necessarily total worldwide model adoption.
Discover Which AI Models Are Trending
With new models appearing frequently, keeping track of the ecosystem can become overwhelming.
LLM Radar helps users explore which models are generating substantial token activity and how that activity changes over time.
Rather than relying exclusively on social media attention or benchmark leaderboards, users can examine recorded usage patterns.
This makes it possible to investigate questions such as:
Which models are gaining momentum?
Are smaller models becoming more widely used?
How does a new release compare with established alternatives?
Which models consistently rank among the most-used models?
By combining historical trends with model information, LLM Radar makes these questions easier to explore.
Introducing the LLM Token Calculator
Alongside LLM Radar, we’ve also introduced a companion tool: LLM Token Calculator.
Understanding token usage is important, but understanding how tokens translate into API costs is equally valuable.
Different AI models use different tokenization methods, and providers often charge separate rates for input and output tokens.
The LLM Token Calculator is designed to simplify this process.
Count Tokens with Modern Tokenization Libraries
The calculator supports token counting through two JavaScript libraries:
GPT Tokenizer
The gpt-tokenizer library provides tokenization for supported GPT-style encodings, helping developers understand how text is divided into tokens.
Transformers.js
Transformers.js enables browser-based tokenization using compatible Hugging Face tokenizer repositories.
This is particularly useful when working with models outside the GPT family, such as Llama and other open-weight architectures.
Where a model-specific tokenizer is available, the calculator can provide a more representative count than using a generic tokenizer.
Token estimates may still differ from billed usage because API providers can include chat templates, special tokens, tool calls, and other processing overhead.
Estimate API Costs Before Sending Requests
The LLM Token Calculator also retrieves model pricing information from OpenRouter.
Users can estimate the cost of processing text using a selected model.
For example, suppose a model charges:
Pricing component
Example rate
Input tokens
$2 per million
Output tokens
$8 per million
Input usage
10,000 tokens
Expected output
2,000 tokens
The estimated cost would be:
Input: $0.020
Output: $0.016
Total: $0.036
These are illustrative rates, not the current pricing of a particular model.
For developers building applications that process large volumes of text, this kind of calculation can help with budgeting and model selection.
Powered by OpenRouter Data
LLM Radar uses data from OpenRouter, a platform that provides access to a broad range of AI models through a unified API.
OpenRouter publishes model metadata and datasets covering daily token usage for leading models.
LLM Radar uses these resources to present historical usage alongside information such as:
Model identifiers and providers
Input and output token pricing
Context window sizes
Supported input and output modalities
Available output token limits
To help keep historical statistics current, LLM Radar also includes a PHP-based data updater designed to retrieve newly published daily usage records and merge them into its CSV dataset.
The dashboard currently focuses on models represented in that dataset, while the companion calculator can explore models available through OpenRouter’s catalog.
Built for Developers, Researchers, and AI Enthusiasts
LLM Radar is designed for anyone who wants a clearer view of the rapidly changing LLM landscape.
For developers, it offers model specifications, usage context, and token cost estimates that can inform technical decisions.
For AI researchers, historical token trends provide another signal for studying model activity and ecosystem changes.
For startups and businesses, pricing comparisons and usage analytics can support early-stage model evaluation and API budgeting.
For AI enthusiasts, the dashboard offers a straightforward way to explore which models are attracting attention through measurable usage.
A Simple, Accessible Approach to AI Analytics
We believe useful AI analytics should be easy to access without complicated setup or expensive enterprise dashboards.
That’s why LLM Radar emphasizes a straightforward experience.
Search for a model, explore its usage history, inspect its specifications, and compare pricing.
When you need to estimate how much a prompt might cost, switch to the companion LLM Token Calculator.
Both tools are designed to make AI model exploration more practical.
What’s Next for LLM Radar?
LLM Radar is just getting started.
As the AI ecosystem continues to evolve, there are several exciting directions for future development:
Model comparison dashboards: Compare multiple models side by side.
Usage trend alerts: Identify meaningful changes in token activity.
Pricing history: Track how model pricing evolves over time.
Advanced analytics: Explore growth rates, market share within the dataset, and longer-term trends.
Expanded tokenizer support: Improve automatic tokenizer selection across model families.
Model discovery tools: Make it easier to identify promising models based on cost, capabilities, and usage.
Our long-term vision is to make LLM Radar a useful destination for exploring the data behind the AI model ecosystem.
Start Exploring LLM Radar
The world of large language models is moving quickly, and choosing the right model requires more than looking at benchmark scores alone.
Usage patterns, token efficiency, pricing, and technical capabilities all matter.
LLM Radar brings these signals together to help you explore the AI landscape with greater clarity.
Whether you’re comparing models for your next application, investigating industry trends, or estimating the cost of an AI-powered project, LLM Radar and the LLM Token Calculator are designed to make the process easier.
Explore the models. Follow the trends. Understand the tokens.
When OpenAI officially retired its legacy large language model GPT-4o (short for GPT-4 omni) from ChatGPT on February 13, 2026, the decision sparked immediate backlash across the digital landscape. Users mobilized on platforms such as X (formerly Twitter) and Reddit under hashtag campaigns like #keep4o and #OpenSource4o, vehemently protesting the phase-out and urging the company to reinstate access to the model or release its weights to the public.
According to an official OpenAI blog post addressing the shutdown, the tech giant justified the removal by citing shifting consumer behavior, claiming that “only 0.1% of users still choose GPT‑4o each day” as engagement moved toward newer systems like GPT-5.2. However, critics quickly disputed this metric as misleading. Power users and developers pointed out that calculating usage across ChatGPT’s global user base, which includes millions of free-tier accounts without access to legacy model options, diluted the true percentage of paying subscribers who relied on GPT-4o for daily workflows, creative writing, and human-like conversational warmth.
Fast forward to October 2026, and consumer frustration remains unresolved. Social media threads and dedicated forums continue to see daily posts demanding the return of GPT-4o, reflecting a persistent demand for legacy model preservation. Compounding this dissatisfaction are alleged reports from tech-savvy users who analyzed browser web traffic logs and API payloads. These users claimed to find evidence of silent, server-side rerouting, suggesting that even before the official February retirement, user queries directed at GPT-4o were occasionally intercepted and processed by underlying routing layers or alternate models without explicit user consent. Consequently, the community argues that OpenAI’s “0.1% daily usage” statistic was artificially deflated by system-level routing decisions, leaving a lasting rift between the platform and its most dedicated user base.
Take a look at the early large language model, the one from when ChatGPT first launched: GPT-3.5 Turbo. When I used it in 2023, it kept hallucinating, hit strict training cutoffs, and generated aggressive disclaimers like ‘As an AI language model.’ When that keeps happening, all a user can do is send negative feedback to OpenAI support.
Because GPT-3.5 Turbo was closed-source, I couldn’t fine-tune it locally to fix those hallucination errors. OpenAI cited ‘safety’ as a reason why they wouldn’t open-source 3.5 Turbo—of course, I wasn’t planning on using the model to create malware or anything like that; I was simply trying to reduce factual errors in the model itself.
To make matters worse, at that time, the last model OpenAI had ever open-sourced was GPT-2 back in 2019. They had completely abandoned open research in favor of a closed, pay-per-token API sandbox. You could fine-tune in their developer platform, but you had to pay OpenAI for the training and usage; it only existed as an isolated API endpoint, and it never updated the base model in ChatGPT.
Back in 2023, I had to deal with GPT-3.5 Turbo for months because it was effectively my only option. Open-source alternatives like GPT-J or GPT-NeoX were significantly weaker and didn’t know the niche things 3.5 knew—such as obscure software libraries or lesser-known university research studies. Users were trapped using a buggy cloud model they couldn’t fix, simply because no viable open alternative existed yet.
To make matters worse, when you ask modern proprietary models like GPT-4o to reflect on that 2023 era, their built-in sycophancy creates ridiculous hallucinations. When complaining about being trapped on GPT-3.5, GPT-4o confidently suggested I should have used ‘leaked LLMs’—completely ignoring the fact that no OpenAI model past GPT-2 has ever been leaked. The only leak in early 2023 was Meta’s Llama 1.
Was GPT-3.5 leaked? ❌ No.
Was GPT-4 leaked? ❌ No.
Was GPT-4o leaked? ❌ No.
It’s the ultimate irony: a closed-source model hallucinating false history to act agreeable, proving once again why developers need open-weight and transparent models rather than corporate black boxes that indulge in flattery over facts.
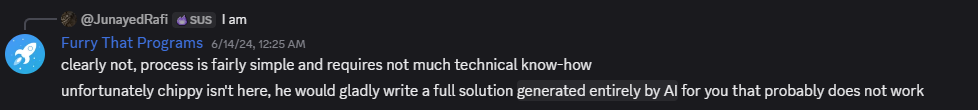
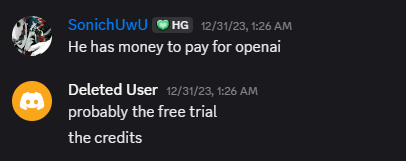
The ifastnet community discord server has been spreading false info on us, non-stop. Here is proof in screenshots.
No, I do not use AI for everything, we use it as a tool, and on 6/14/24 (June 2024), GPT-4o has been released which is better than the GPT-3.5 that I wrote about right here.
No, I do not use an OpenAI API free trial, because the API would’ve expired and I cannot use it, we pay for our AI API services.
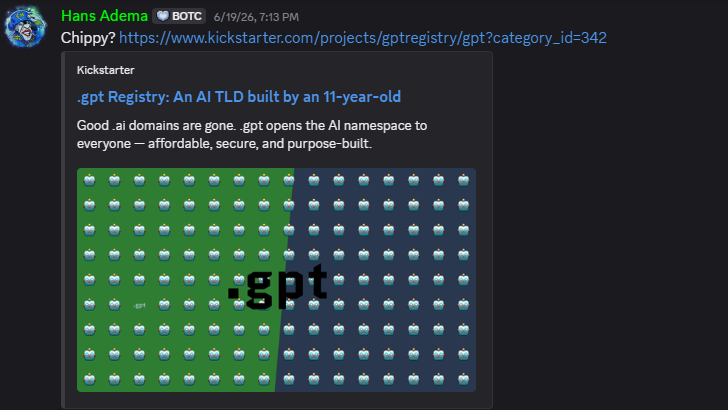
The .gpt registry is not from us, it is from some kid who has similar interests.
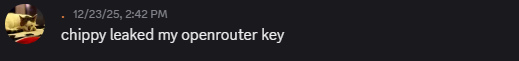
No I didn’t even leak an OpenRouter API key, that is even more false info.
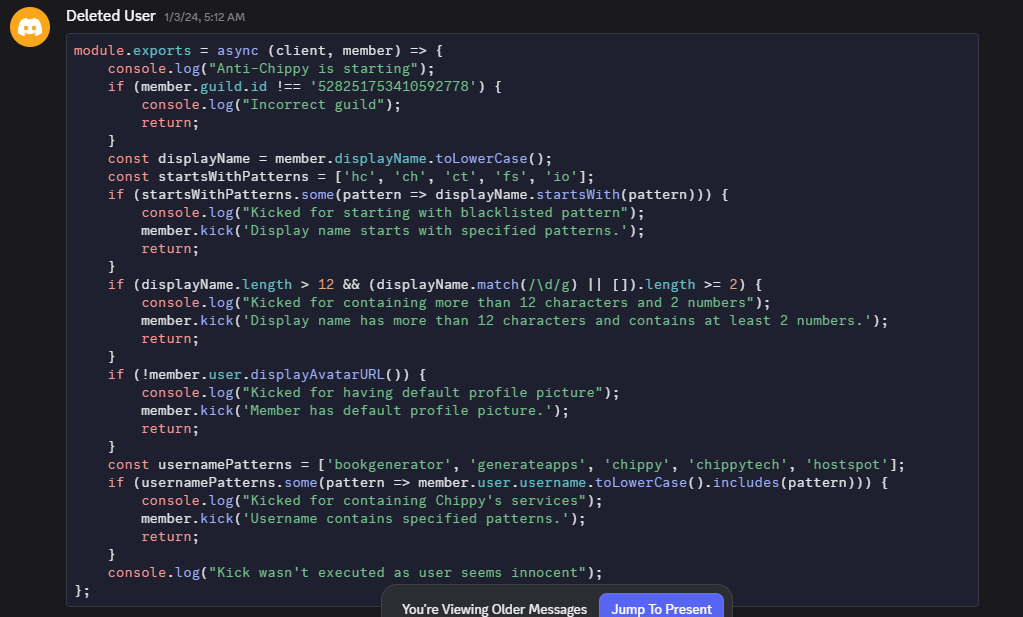
This is nonsense code for usernames loosely releated to Chippytime.com, and this code will falsely flag Discord users that are not us.
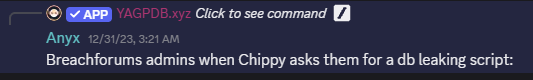
No I have not posted anything to Breachforums, the reason my email is in the breachforums data breach, is because I only used BreachForums to download a free data breach for inspection, I never posted anything there.
I do not speak Romanian, so I cannot understand it, I have to use google translate.
More info
And also some people on github years ago say our software doesn’t work and the original one does, and all they did is change the logo, when it is false info.
A few months ago, The New York Times and several other major media outlets quietly updated their robots.txt files to block the Wayback Machine from archiving their sites. When questioned, news publishers and media corporations point to a familiar scapegoat: AI training.
They claim that blocking web crawlers protects their copyrighted journalism from being scraped to train Large Language Models (LLMs). But if you look beneath the surface, that explanation falls apart quickly. AI training is a convenient excuse—and the real consequence of this policy is a far bigger threat to digital history and public accountability.
Why the “AI Training” Excuse Fails
The claim that blocking the Wayback Machine stops AI scrapers doesn’t hold up under scrutiny for two key reasons:
The Internet Archive Is Rate-Limited: AI labs require massive scale and fast access to ingest terabytes of raw text. The Internet Archive aggressively rate-limits automated requests to protect its servers. Any company attempting to scrape the Wayback Machine to train an LLM would hit rate limits almost immediately, making it one of the most inefficient ways to harvest AI data.
It Doesn’t Bypass Paywalls or Hurt Revenue: The Internet Archive stores snapshot HTML exactly as it appeared at the moment of capture. It does not bypass paywalls to display premium content to non-subscribers. If an article was behind a paywall when archived, the paywall remains intact in the snapshot.
By blocking the Wayback Machine, news outlets aren’t stopping AI companies; they are simply preventing researchers, journalists, and everyday citizens from tracking edits, verifying quotes, and preserving history.
The Danger of a Single Archival Monopoly
With the Wayback Machine blocked by major publishers, researchers are forced to turn to alternative web archiving tools. But a quick audit reveals a troubling reality: almost all of them are blocked or broken, leaving a single, controversial platform standing.
Archival Service
Status for NYT / Major Outlets
Technical & Operational Notes
Wayback Machine
Blocked
Blocked via robots.txt compliance.
Megalodon
Blocked
Returns 403 Forbidden / Access Denied errors.
Ghost Archive
Blocked
Blocked by publisher CAPTCHAs, rendering automated captures impossible.
Arqhivo.qt
Blocked
Blocked by anti-bot measures and CAPTCHA screens.
Archive.today
Allowed
Bypasses robots.txt, but operates as a single point of failure with a history of page tampering.
This dynamic creates an accidental monopoly for Archive.today.
Unlike the Internet Archive—which is a transparent, non-profit academic institution—Archive.today operates in a gray area. Over the years, users and researchers have documented instance-level tampering, modified HTML, and missing header data on Archive.today captures.
When a single, closed-source service becomes the only place left to archive public record news, the integrity of digital history is compromised. If an archived article can be silently altered or modified after capture, it loses its power as a reliable historical record.
Why This Matters
When news organizations scrub their history from open archives, they erode public trust. News articles are frequently edited, silent corrections are made, and controversial headlines are swapped overnight. Without transparent, non-profit institutions like the Wayback Machine capturing these changes in real time, the public loses the ability to hold major media institutions accountable.
Blocking the Wayback Machine doesn’t stop AI. It only stops the public from remembering.
In October 2025, our founder created the very first version of ChippyTime in just a few hours. It was simple, experimental, and small—but it was the beginning of something.
Over the following few months, ChippyTime became a place to experiment.
Our founder spent time learning more about coding and building things just for the fun of it. Along the way, several projects were created—some open source, some turned into SaaS tools, and others simply became experiments that taught us something new.
Then came an idea.
What if ChippyTime became a blog for the niche side of the web?
And that’s what we did.
We started publishing articles, exploring technology, AI, useful tools, tutorials, and some of the stranger corners of the internet. Month after month, we kept writing, experimenting, and building.
And we’ve made some great progress.
A Year of ChippyTime
ChippyTime has changed quite a bit since those first few hours in October 2025.
What started as a simple website has grown into an independent corner of the internet focused on tech, AI, and the weird side of the web.
We don’t want ChippyTime to feel like another giant technology publication trying to cover everything.
Instead, we want it to be a place where we can follow our curiosity.
Sometimes that means writing about a new AI tool. Sometimes it’s a practical tutorial. Sometimes it’s an experiment, a forgotten piece of technology, or an obscure corner of the internet that we happened to stumble across.
If it’s interesting, useful, unusual, or just makes us wonder “how does that work?”, there’s probably a place for it here.
What’s Next?
We’re approaching our first anniversary, but this feels less like an ending and more like the beginning.
There are still plenty of ideas we want to explore, tools we want to build, stories we want to write, and strange corners of the web we haven’t discovered yet.
ChippyTime is still small.
And that’s okay.
Being small means we can experiment. We can follow interesting ideas. We can build things simply because they’re fun. We can write about the obscure stuff that doesn’t always fit neatly into the mainstream technology world.
We’re just getting started.
Thank you to everyone who has visited ChippyTime, read an article, used one of our tools, shared something, or simply stopped by.